Data Governance in Financial Services Across Business Lines
Siloed data governance turns AI-driven decisions into compounding risk across business lines.
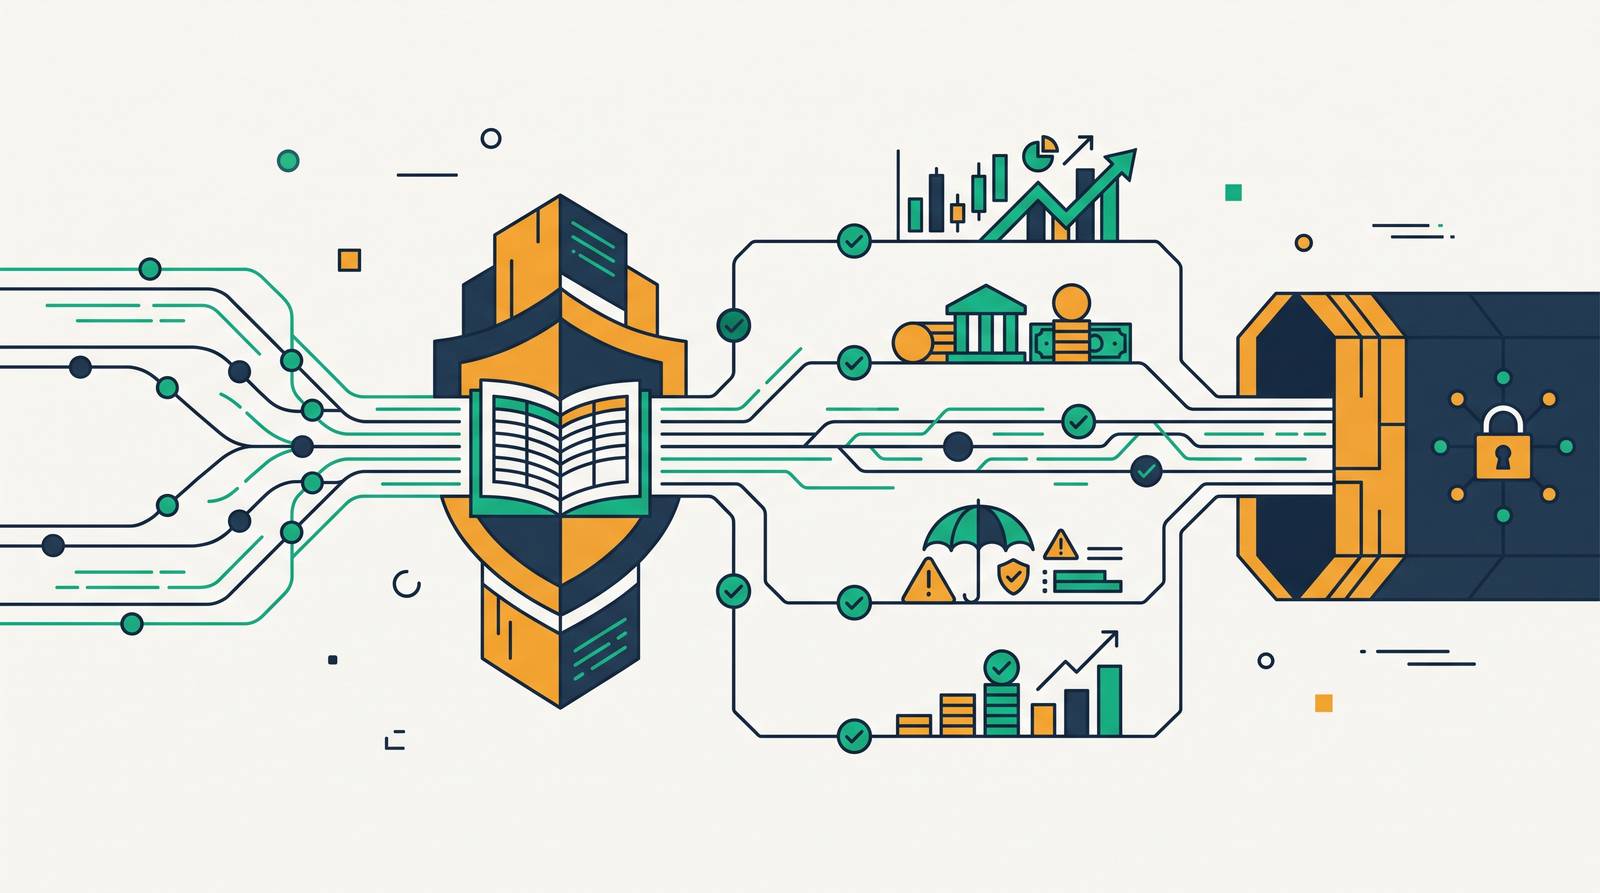
Data governance in banking has a business-line problem, and it's about to get more expensive. Most banks and credit unions still treat governance as something each department owns on its own: compliance holds its data, lending holds its data, payments holds its data. That made sense when each line ran its own operation, answered to its own regulator, and rarely had to share a data model with the line next door. AI systems that act on that data, rather than just report on it, are exposing the gap fast, and the old structure is running out of road.
How business-line silos turn data inconsistencies into compounding risk
Walk into most institutions and you'll find lending, payments, risk, compliance, treasury, and operations each running their own data dictionaries, their own quality checks, their own rules for who gets to see what. Nobody sat down and designed it this way. It grew one department at a time, over years, the way most large organizations grow, and by the time anyone notices the seams, there are a dozen of them.
A few things go wrong when data lives like this, and none of them look the same from the inside.
Definitions drift first, and nobody notices day to day, since "customer risk score" in lending doesn't mean quite the same thing it means in AML. Run a cross-line analysis, though, and the inconsistency is sitting right there, quiet until something forces it into view.
Next, lineage breaks at the seams between systems. Say a payment gets flagged by fraud monitoring, and that flag shrinks a customer's credit limit. Which system holds the full record of what drove that outcome, and why? Usually none of them, not completely, because the record is scattered across systems that were never built to talk to each other.
Policy, meanwhile, just doesn't travel. Retention rules, access permissions, classification standards: whatever gets set in one line doesn't automatically carry into the next. Each business line ends up running its own small regulatory universe, with a rulebook nobody outside that line has read.
None of this stays theoretical for long. It surfaces the moment an examiner asks for the data trail behind a specific decision, and the institution has to piece it together by hand from systems that don't share a common language. Deloitte's 2024 banking survey found most bank data users say the data they need is often unavailable or takes too long to pull. That's fragmentation showing up as delay.
A data quality problem in one line quietly drags down decisions everywhere else that touches shared customer data, without tripping any alarm. It shows up later, in a bad decision nobody can trace back to where it started, and that risk was tolerable when a person made each call, case by case, with judgment as the backstop. Automated systems change the calculation entirely: the moment they pull from the same flawed foundation at transaction speed, with nobody standing there to catch it, that old tolerance disappears.
What a unified governance framework actually covers across business lines
Unified governance means the same standards apply everywhere, with clear ownership at every point data gets touched. A central office can't dictate everything top-down, and no single line gets to quietly keep running its own show underneath a shared logo.
A few things have to span every line for this to hold together. One data dictionary for the whole institution: customer, account, risk rating, beneficial owner, all defined the same way everywhere, with no line allowed to quietly override the definition for its own convenience. Lineage tracking that actually traces, so any data point behind any decision can be followed back to its source, through every system it passed on the way. Quality thresholds that don't bend by department: completeness, accuracy, timeliness held to the same bar for every system feeding an AI-driven workflow, not whatever bar each line happened to set for itself years ago. Access and classification rules that work the same whether the person asking sits in credit risk or in treasury. And named accountability at the line level, owners who answer to institution-wide standards rather than just their own team's quarterly targets.
This has to reach into the AI lifecycle too, covering how training data gets picked and checked, how model drift gets caught, and how an AI-driven decision gets logged so it holds up for internal audit and an outside examiner both. The OECD's AI Principles and the EU AI Act both treat solid governance of data processes as the floor trustworthy AI has to stand on.
There's a real gap between governance as a periodic audit exercise and governance running underneath daily operations, continuously. Institutions still doing the former are worse positioned, structurally, to produce the evidence AI-driven workflows now demand on short notice.
How governance requirements differ by business line — and where they must converge
Each line carries its own version of this problem, but how that plays out day to day is worth walking through. Look at where the requirements pull apart, and where they have to come back together.
Lending needs data that's accurate, consistent, and explainable enough to hand a regulator on request, especially for adverse actions. Income and employment verification increasingly runs through automated agents now, and any gap in quality or lineage there carries direct fair-lending exposure. The tools processing loan documents can move fast, but whether the data feeding them meets the same bar a human underwriter was held to is the part worth asking about.
Payments leave almost no window for a person to step in and double-check anything. Governance has to work well enough that automated systems act correctly without pausing for a manual check the rail's speed won't allow anyway. Payment data crosses core banking, SWIFT, FedNow, and internal general ledger systems, so lineage across those touchpoints is what lets someone resolve an exception without a multi-day investigation. Straight-through processing depends on clean, consistently defined data going in, and bad data in means expensive exceptions out, which erodes the exact efficiency automation was supposed to deliver.
Risk and AML teams build behavioral profiles from data spanning multiple lines: transaction history, account activity, onboarding records. The quality of those profiles depends on whether the data underneath is governed the same way across all of them. AI-driven AML tools can meaningfully cut false positive rates, but only when the behavioral baseline sits on clean customer data, and weak governance underneath the model does more damage than a weak model ever could.
Compliance and regulatory reporting pull from every line at once. One inconsistency in how a field gets defined or populated can turn into a material discrepancy in a report regulators take seriously. Industry observers have noted that institutions running integrated governance frameworks tend to fare better in examinations than those piecing compliance records together by hand after the fact.
The convergence point across all four is customer identity data. It sits underneath everything, and a stale address, an inconsistent beneficial ownership record, or an unresolved duplicate customer file propagates into every line's decisions at once, because every line draws from the same well.
Why AI agents executing transactions raise the governance stakes beyond what analytics alone required
Here's the distinction that actually matters: an AI system that surfaces a recommendation leaves a person to make the final call, and that person absorbs whatever data quality problem might be lurking underneath. An AI system that executes the transaction has a different profile entirely, acting on whatever data it gets, at whatever speed the system runs, with no one standing between the input and the outcome.
When a payment transfer, a credit line adjustment, or a collections outreach gets executed by an AI agent instead of a person, the governance architecture is the safeguard. There's no human review step left to catch a bad input before it becomes a completed action.
Multi-agent setups make this worse. Picture a workflow where one agent pre-screens, a second flags anomalies, a third executes, each handing data to the next in line. A governance gap at step one rides through the whole chain, and it's often invisible until a downstream decision is already done and can't be undone. S&P Global has warned that automation now links trading, credit, and compliance systems across institutions through continuous data exchange, creating conditions where agents respond to the same data shock in correlated ways that no single institution's governance framework fully contains on its own.
The explainability gap is what makes this more than a faster version of an old problem. When the OCC or the SEC audits a specific transaction, they want the logic behind it: what data got used, what thresholds tripped, what policy constraints were active at the time. An AI system executing on poorly governed data can't produce that account, because the inputs it worked from were never reliable or traceable to begin with, and there's no reconstructing an audit trail after the fact when the underlying data was never solid to start with.
That's why the governance bar for AI execution sits higher than the bar for AI analytics. The audit trail has to be native to the execution layer itself, captured the moment the action happens, not stitched together afterward from logs scattered across disconnected systems, since there's no remediation window once a transaction has gone through. Institutions putting agentic AI onto existing banking rails need infrastructure built with this in mind from day one: configurable controls, complete audit trails, and permission structures that enforce policy at the point of execution rather than somewhere downstream of it.
The regulatory landscape institutions must navigate — and what it demands of governance architecture
The regulatory picture is splitting into pieces rather than converging into one clear standard, and institutions operating across borders feel that most directly.
The EU AI Act, in force since August 2025, requires heavy transparency measures, risk assessments, and documentation for AI systems used in high-stakes decisions, credit and financial services included. Germany's BaFin, in guidance issued December 2025, places AI risk squarely inside ICT risk management under DORA, treating it as a regulated operational risk with real supervisory teeth behind it. The Bank of Thailand, in 2025 guidance, requires a human in the loop whenever AI handles strategic functions like credit approval, account opening, deposits, withdrawals, or transfers, and mandates controls spanning the full lifecycle, from data quality through model evaluation, explainability, and AI-specific cyber defenses. In the U.S., California's AB 1018 defines "consequential decisions" to include anything that materially affects the cost, terms, or accessibility of financial services. It passed the Assembly in mid-2025, and an attempt to attach federal preemption got stripped out by the Senate shortly after.
All of this points toward a sliding scale: scrutiny tracks the risk and impact of the use case. Routine automation draws lighter requirements, while AI executing credit, payment, or compliance decisions faces the full weight of the demand. That raises a real question for architecture: build to the minimum bar in your home jurisdiction, or build to the toughest requirement anywhere you operate? Frameworks built for explainability, auditability, and human oversight in high-stakes execution travel better across borders than frameworks calibrated to whatever the loosest regulator happens to require.
Supervisory technology is changing the examination dynamic too. Regulators can increasingly analyze submissions and catch inconsistencies close to real time, so the old tolerance for manually assembled, after-the-fact compliance records is shrinking fast. Institutions running continuous governance, with live lineage, native audit trails, and consistent standards across lines, are simply better positioned for this than institutions still treating governance as an annual event.
Building governance that works across lines in practice — architecture choices that hold under examination
There's a foundational choice every institution ends up making, whether it names it out loud or not: governance built into how systems execute, or governance bolted onto systems that were never built with it in mind.
The retrofit route tends to produce documentation that satisfies a checkbox on an exam but doesn't reflect how decisions actually get made day to day. Governance native to the execution layer, where every AI action gets checked against policy before it runs and logged the moment it happens, produces evidence that holds up under examination precisely because nobody had to assemble it after the fact.
A few things separate what holds up from what doesn't. Policy enforcement has to happen at the point of execution: systems need to check whether a proposed action is authorized under current policy before it runs, rather than flagging problems in a report the next day. Audit logs need to be immutable, capturing what happened alongside what data inputs, model versions, and policy constraints were active at that exact moment. Cross-system lineage needs to answer a question directly: an examiner asks what data drove a decision, and the system gives a traceable answer without anyone reconstructing it by hand. Model governance, in turn, has to track provenance and drift across every model in production, including where its training data came from and how it's changed since.
Institutions building on existing core systems, payment rails, and CRM layers tend to move faster and carry less transition risk than those ripping everything out to start fresh. They build the governance layer to work with what's already running underneath, rather than discarding a data foundation they've spent years building.
Backbase's launch of its AI-native Banking OS is one example of this in product form. Its Sentinel authority layer checks every actor's permissions against bank policy before an action executes, and logs each one as it happens; it's already running at institutions including Navy Federal Credit Union and TD Bank.
Voice and text interfaces that execute real transactions need this same discipline extended to the interface itself. The permission checks, the audit logging, the policy constraints that apply when a human teller processes a transfer also need to apply when a voice assistant starts that transfer instead. Agentic AI platforms built specifically for financial services, where SOC 2 certification, configurable controls, and full audit trails come standard rather than as an add-on, fit this architecture in a way that general-purpose automation tools retrofitted for banking usually don't.
Where financial institutions typically get stuck — and how to move past the governance plateau
AI use across financial services has grown a lot, but a good share of institutions still say governance and security worries are their main obstacle to going further, and that points to a structural problem sitting underneath the data itself.
A few sticking points come up again and again. Data quality is the constraint most often named: most bankers point to data quality or accessibility as their top obstacle to AI adoption, and no governance framework, however well built, can make up for source data that's unreliable at the root. Governance can enforce consistency, but manufacturing accuracy out of records that were never accurate to begin with sits beyond what any framework can do.
Accountability gaps run close behind. Unified governance needs named owners who answer across lines, not just within their own team, and most institutions haven't restructured who's accountable to match how ambitious their data plans actually are. The org chart hasn't caught up to the strategy deck.
Mindset is the harder problem: institutions that treat governance as a cost center rather than operational infrastructure tend to underinvest, right up until an exam forces the issue and the underinvestment becomes visible to everyone in the room at once.
Per McKinsey, only a small share of organizations have full visibility into their AI training data, and most institutions are running AI on a foundation they can't fully describe. It's hard to govern something you can't fully see. That's the plateau, and getting past it starts with treating data quality and lineage as the prerequisite, not a side project running alongside AI deployment.